AI Research
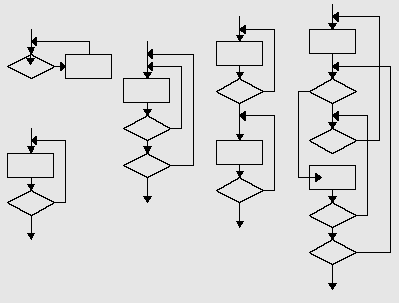
Inference-time AI Evaluation Methods: Loop through validation code, judge models and human monitors
Production AI systems need layered test-time evaluation driven by model confidence scores. Code-based business rules validate every response. Model judge panels catch edge cases when confidence dips. And for the highest-stakes scenarios, a virtual situation room of human experts and peer reviewers provides the ultimate quality gate. The key: not every answer needs the same scrutiny. Let confidence drive the escalation.
Read more →