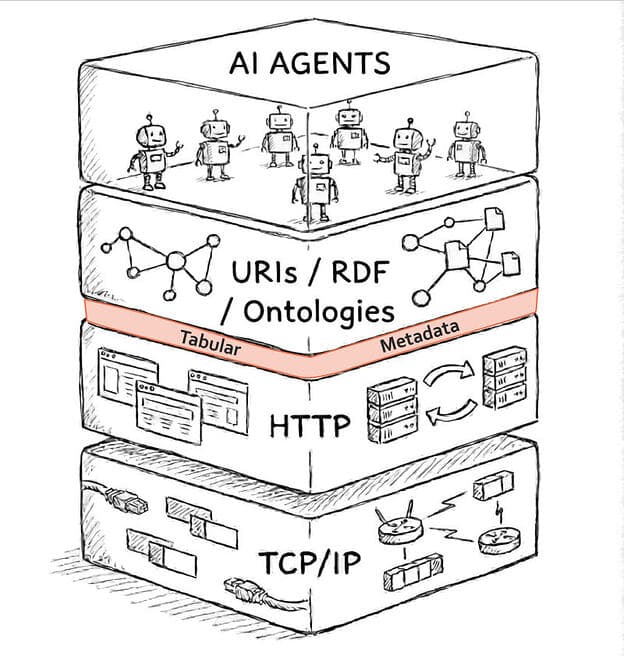
1.1 The Schema Design: Mapping the Territory
To operationalize the “Row-per-paragraph” concept, we must define a robust schema that captures the multidimensional nature of the data. This schema serves as the “Map,” translating the raw territory of documents into a navigable structure. A recommended schema for a Fact_paragraphs Delta table would be structured as follows:
Timestamp of ingestion to support temporal filtering.
1.1.1 Rationale for Structural Columns
- Sequence_Index: One of the most significant limitations of vector databases is the loss of adjacency. A vector search might retrieve paragraph #45 because it is relevant, but paragraph #46 might contain the crucial exception (“…however, the above clause does not apply if…”). By storing the sequence index, the retrieval engine can fetch the “neighborhood” of the hit (e.g., WHERE Document_UUID = X AND Sequence_Index BETWEEN 44 AND 47), restoring the narrative flow often lost in chunking.
- Section_Path: A paragraph that simply reads “The threshold is 5%” is semantically ambiguous. Does it refer to a price variance, a toxicity limit, or a delivery delay? By storing the hierarchy in the row (e.g., “Quality Assurance > Chemical Composition > Impurity Limits”), the chunk becomes self-describing. This resolves the ambiguity that purely semantic vectors often struggle with.
- Entities_JSON: This column acts as the bridge to GRAPHRAG. Instead of requiring a separate Graph Database, we can store node relationships directly in the row. A query can then identify all paragraphs that mention “Project Apollo” and “Vendor Y” simultaneously, effectively simulating a hyper-edge connection between these entities.
1.2 The Metadata Strategy: Avoiding the Explosion
A significant risk in this architecture is the “Metadata Explosion”. Documents possess rich, inherited metadata (e.g., a paragraph in a contract inherits the contract’s execution date, the counterparty’s name, the governing law). Replicating all file-level metadata into every paragraph row is inefficient and leads to data anomalies if the file metadata changes.
The solution is a Star Schema approach within the Lakehouse:
- Dim_Documents: Stores file-level attributes (Filename, Path, Author, Creation Date, Security Class, Version).
- Fact_paragraphs: Stores the atomic content and paragraph-level attributes (Entities, Sentiment, Vector).
At query time, the retrieval engine performs a high-performance join to filter paragraphs based on document attributes. Modern lakehouse engines optimize these joins natively, making them fast even at scale. For example: "Find me paragraphs about 'indemnity' (Fact) from contracts signed in 2023 (Dim)."
1.3 Storage Infrastructure: Lakehouse Platforms and Open Table Formats
The Tabular GRAPHRAG architecture is platform-agnostic by design. It requires only three foundational capabilities from the storage layer: (1) ACID-compliant open table formats for structured paragraph storage, (2) a SQL engine capable of metadata filtering and star-schema joins, and (3) a vector search service for semantic retrieval. No single vendor currently offers a turnkey "Tabular GRAPHRAG" button, but every major lakehouse platform provides the necessary building blocks.
- Open Table Formats (Delta Lake / Apache Iceberg): The Fact_paragraphs table is stored in an open columnar format (Delta Parquet or Iceberg on Parquet). These formats provide ACID transactions, schema evolution, and time-travel queries. The raw source documents (PDFs, images) reside alongside the parsed tables in cloud object storage (S3, GCS, ADLS, or MinIO).
- Databricks (Unity Catalog + Mosaic AI Vector Search): Delta tables are governed by Unity Catalog with row-level security. Mosaic AI Vector Search creates auto-syncing vector indexes directly from Delta tables, supporting hybrid search (semantic + keyword) with metadata filtering.
- Snowflake (Cortex Search): Cortex Search is a fully managed hybrid search service combining vector and BM25 keyword retrieval. Snowflake's native row-level security policies and Iceberg table support make it a strong fit for governed RAG workloads.
- Google BigQuery (VECTOR_SEARCH + ML.GENERATE_EMBEDDING): BigQuery provides serverless vector search natively in SQL, combined with standard WHERE clauses for metadata filtering. Row-level security is built in, and the entire pipeline stays within the data warehouse.
- AWS (Iceberg + OpenSearch Serverless + Lake Formation): Apache Iceberg on S3 provides the lakehouse storage layer. Amazon OpenSearch Serverless handles vector and hybrid search. AWS Lake Formation enforces row-level security via LF-Tags, enabling fine-grained access control across the paragraph table.
- Microsoft Fabric (OneLake + Azure AI Search): OneLake provides a unified storage namespace with Delta Parquet tables. Azure AI Search serves as the vector index with HNSW and hybrid retrieval. Fabric's V-Order optimization accelerates read performance for metadata-heavy scan patterns.
- Fully Open-Source Stack: Delta Lake or Apache Iceberg for table format, Apache Spark or Trino for SQL, and Qdrant, Milvus, or Weaviate for vector search. This avoids any proprietary control plane, though it requires more operational overhead.
2. The Ingestion Pipeline: The Manufacturing of Knowledge
Transforming the “Territory” (raw PDFs/images) into the “Map” (structured rows) requires a sophisticated ingestion pipeline. This is not a simple text extraction; it is a knowledge manufacturing process. The pipeline must discern structure, extract meaning, and compute vectors.
2.1 Stage 1: Layout-Aware Extraction (The Cartographer)
Standard text extraction libraries often discard the visual layout of a document, flattening columns and headers into a confused stream of text. To maintain the fidelity of the territory, we employ layout-aware extraction services such as Azure AI Document Intelligence, Amazon Textract, or Google Document AI.
- Layout Analysis: The Layout model identifies the document structure: titles, section headers, tables, and footers. It understands that a block of text in bold, larger font is a parent node in the hierarchy.
- Table Preservation: A critical failure of standard GRAPHRAG is the destruction of tabular data inside documents. If a PDF contains a pricing table, standard extraction might render it as a jumbled string of numbers. Layout models extract the table as a table (JSON grid). In our architecture, a table can be stored in two ways:
- As a Markdown-formatted string within the Content_Text column of a single paragraph row.
- As a set of relational rows in a separate Fact_Extracted_Tables table, linked by Document_UUID.
- Visual Elements: The pipeline can detect charts and diagrams. Using a multimodal model (like GPT-4o), we can generate a descriptive caption of the chart (e.g., “Line graph showing Q3 revenue growth of 15%”). This caption is stored in the Content_Text column, making the visual data searchable via text/vector queries.
2.2 Stage 2: Semantic Chunking and Parsing
Once the layout is understood, the “Flattener” logic converts the hierarchy into rows.
- Logic: Instead of cutting text every 500 tokens, we cut at the paragraph boundary identified by the Layout model.
- Context Injection: As the parser walks down the document tree (Chapter 1 → Section 1.2), it maintains a “state” of the current headers. When it writes the paragraph row, it injects this breadcrumb trail into the Section_Path column. This ensures that even short paragraphs (e.g., “None.”) carry their full semantic weight (e.g., “Exceptions > Financial > None”).
2.3 Stage 3: AI-Driven Enrichment (The “AI Skill” Injection)
This is where the "Metadata for each row" requirement is satisfied. We use ETL tools native to the lakehouse platform—such as Databricks Notebooks, Snowflake Snowpark, Fabric Dataflow Gen2, or Apache Spark—to apply AI-driven transforms.
- Mechanism: We invoke a lightweight LLM (or a specialized AI Skill) for each row (or batch of rows).
- The Prompt: “Analyze this paragraph. Extract key entities (Person, Org, Location). Classify the topic from this taxonomy:. Determine the sentiment (-1 to 1).”
- The Output: The model returns a structured JSON object.
- Integration: This JSON is written into the Metadata_Tags and Entities_JSON columns.
This step effectively “pre-computes” the understanding of the text. Instead of forcing the retrieval LLM to figure out the topic at query time (which is slow and expensive), the metadata filter can simply select WHERE Metadata_Tags.Topic = ‘Legal’.
2.4 Stage 4: Vectorization
The final step in the factory is generating the embedding vector for the Content_Text. Using models like text-embedding-3-small, we generate a floating-point array that captures the semantic essence of the paragraph. This array is stored in the Content_Vector column, ready for indexing.
3. The Tri-Hybrid Retrieval Engine: Orchestrating SQL, Vector, and Graph
The core innovation of the Tabular GRAPHRAG architecture is Hybrid Retrieval. It moves beyond the naive “Cosine Similarity” to a multi-stage, multi-modal retrieval strategy that leverages the full tabular structure.
3.1 The Three Modes of Retrieval
The architecture enables a “Tri-Hybrid” approach, utilizing SQL, Vector, and Graph logic simultaneously.
3.1.1 The Librarian: SQL Filtering (The “Hard” Filter)
The Librarian deals with deterministic facts.
- Mechanism: Standard SQL WHERE clauses or Metadata Filters in a Vector Database.
- Use Case: Security boundaries (WHERE Security_Level <= ‘User_Clearance’), Temporal scoping (WHERE Date > ‘2023-01-01’), Exact attribute matching (WHERE Document_Type = ‘MSA’).
- Value: It aggressively prunes the search space, ensuring zero noise from irrelevant domains. This is critical for preventing “contamination” where an LLM answers a question about “Project Alpha” using data from “Project Beta” simply because they share semantic similarities.
3.1.2 The Researcher: Vector Search (The “Soft” Filter)
The Researcher deals with semantic ambiguity.
- Mechanism: k-Nearest Neighbors (kNN) or ANN (HNSW) search on the Content_Vector column.
- Use Case: Finding concepts, thematic matches, and paraphrased queries. A user asks “How do we handle water damage?” and the system retrieves paragraphs about “fluid ingress remediation” and “moisture control protocols.”
- Value: It bridges the vocabulary gap between the user and the document author.
3.1.3 The Archivist: Graph/Relational Traversal (The “Connected” Filter)
The Archivist deals with relationships.
- Mechanism: Relational joins or graph traversals on the Entities_JSON column.
- Use Case: Multi-hop reasoning. “Find the supplier who provided the battery for the device that failed in the Q3 test.”
- Hop 1: Find the “Q3 test failure” report (Vector/SQL). Extract the device ID.
- Hop 2: Find the “Device Spec” document (SQL Link). Extract the “Battery Component ID.”
- Hop 3: Find the “Procurement Log” (Table). Extract the “Supplier Name.”
- Value: This connects disparate pieces of information that are not semantically similar but are causally linked.
3.2 Fusion and Reranking: Reciprocal Rank Fusion (RRF)
To combine these distinct signals, the architecture employs Reciprocal Rank Fusion (RRF).30 RRF is an algorithm that takes the ranked lists from multiple retrievers (e.g., the Top 50 from Vector Search and the Top 50 from a Keyword/SQL Search) and merges them into a single unified ranking.
- The Formula: 𝑆𝑐𝑜𝑟𝑒(𝑑) =𝑠𝑢𝑚𝑓𝑟𝑎𝑐1𝑘+𝑟𝑎𝑛𝑘(𝑑).
- The Outcome: Items that appear near the top of both lists are boosted significantly. This favors paragraphs that are both semantically relevant (Vector) and contain the precise keywords or attributes (SQL/Keyword) requested by the user.
3.3 Graph Dynamics without a Graph Database
The prompt asks about the hybrid use of Graph technology. A dedicated Graph Database (like Neo4j) is powerful but introduces significant infrastructure complexity. The Tabular GRAPHRAG architecture allows for “Virtual Graph GRAPHRAG” using the relational model.
- Edges as Foreign Keys: The Entities_JSON column acts as a set of edges. If paragraph A contains Entity: “Project X” and paragraph B contains Entity: “Project X”, they are implicitly connected.
- SQL Graph Traversal: We can simulate graph traversal using Self-Joins.
- Query: “Find all risks related to Project X.”
- Step 1: Select paragraphs where Entities contains ‘Project X’.
- Step 2: Identify other entities in those paragraphs (e.g., “Vendor Y”).
- Step 3: Select paragraphs where Entities contains ‘Vendor Y’ AND Metadata_Tags contains ‘Risk’.
- This approach delivers approximately 80% of the value of a dedicated Knowledge Graph (identifying 2nd-degree connections) with 20% of the complexity, leveraging the native SQL engine of the Lakehouse.
4. Implementation Strategy
The theoretical architecture requires a concrete platform.
4.1 AI Agent / AI Skill Configuration
Modern lakehouse platforms introduce the concept of AI Skills or AI Agents—configurable agents grounded in a specific data schema. In Databricks this manifests as Mosaic AI Agent Framework; in Microsoft Fabric, as AI Skills; in Snowflake, as Cortex Analyst. Each is a configurable agent grounded in the Fact_paragraphs and Dim_Documents tables.
- Configuration: The architect defines the table relationships and provides "instructions" (meta-prompts) to the agent.
- Instruction: "When a user asks about 'implications', query the 'Content_Text' but filter by 'Is_Actionable = True' in the metadata."
- Instruction: "Always prioritize documents with a 'Final' status in the Version column."
- Execution: The AI agent accepts natural language, generates the necessary SQL queries (e.g., SELECT TOP 5 * FROM Fact_paragraphs WHERE…), executes them against the lakehouse, and interprets the results to generate an answer.
- Democratization: This allows non-technical business users to interrogate the unstructured data repository using structured logic.
4.2 ETL and Low-Code Ingestion
Each lakehouse platform provides native ETL capabilities for the ingestion pipeline. Examples include Fabric's Dataflow Gen2, Databricks Workflows with Delta Live Tables, Snowflake's Snowpark, or open-source orchestrators like Apache Airflow with Spark.
- Connectors: Native connectors ingest files from cloud storage, SharePoint, databases, and external sources.
- AI Transforms: Most platforms now support inline AI functions in transformation steps—calling embedding models or entity extraction without writing complex code. Databricks offers AI Functions in SQL; Fabric provides AI Transforms in Dataflow Gen2; Snowflake exposes Cortex LLM functions directly in Snowpark.
- Destination: The output is written directly to the Delta or Iceberg tables in the lakehouse, ready for querying.
4.3 Dedicated Vector Index Integration
While lakehouse SQL engines are fast, sub-second vector similarity search at massive scale (millions of vectors) often requires a dedicated index. The architecture bridges the lakehouse and a specialized vector engine through index synchronization.
- Architecture: The paragraph data remains in the lakehouse (Delta or Iceberg Parquet). A vector search service—such as Databricks Mosaic AI Vector Search, Azure AI Search, Amazon OpenSearch Serverless, Snowflake Cortex Search, or Qdrant/Weaviate—is configured with an indexer that monitors the source table.
- Synchronization: When new paragraphs are added to the table, the indexer automatically reads them and updates its HNSW (Hierarchical Navigable Small World) vector index. Databricks and Snowflake handle this automatically; AWS and open-source stacks require a sync pipeline.
- Retrieval: The end-user application queries the vector search service for high-speed retrieval (Vector + Keyword + Metadata Filtering), receiving the paragraph_UUIDs. It can then optionally query the lakehouse SQL endpoint to retrieve the full context or surrounding paragraphs if needed.
5. Governance, Security, and Enterprise Reality
The shift to a Tabular GRAPHRAG paradigm offers significant advantages in governance, addressing the “blind spots” of standard GRAPHRAG.
5.1 Row-Level Security (RLS) as a First-Class Citizen
Vector databases have historically struggled with complex enterprise security models (e.g., “User A can see the vector but not the metadata,” or “User B can only see documents from their department”). By anchoring the data in a relational table (Delta/SQL), we can leverage mature Row-Level Security (RLS) policies.
- Implementation: A Security_Access_List column is added to the paragraph table (or linked via the Document Dimension). The SQL Endpoint enforces policies: Filter rows where User.Department IN (Row.Allowed_Departments).
- Guarantee: This ensures that the retrieval engine never returns a paragraph to the LLM context window that the user is not authorized to see. This is a deterministic security guarantee, unlike the “filter-after-retrieval” patterns often used in pure vector stores, which waste compute and risk leakage.
5.2 VersionGRAPHRAG: Managing Temporal Truth
Unstructured data is not static. Policies change; specifications are revised. A GRAPHRAG system that retrieves an outdated safety protocol is a liability.
- The Temporal Map: The Tabular schema supports Effective_Date and Expiration_Date columns.
- The Query: The retrieval agent is instructed to always append AND Current_Date BETWEEN Effective_Date AND Expiration_Date to its SQL queries.
- Change Detection: By hashing paragraph content, the ingestion pipeline can detect if a new version of a document contains identical, modified, or new paragraphs. This allows the system to answer sophisticated questions like “How has the liability clause changed between the 2020 and 2024 versions of the MSA?”—a query impossible for standard vector GRAPHRAG.
5.3 Data Lineage and Auditability
In regulated industries (Finance, Healthcare), every AI-generated answer must be traceable.
- The Citation: Because every paragraph has a Page_Number and Document_UUID, the AI response can include precise citations: “According to the 2023 Risk Policy (Page 14, paragraph 3)…”.
- The Audit Trail: Modern lakehouse platforms provide full lineage tracking. We can trace the answer back to the specific row in the Delta or Iceberg table, back to the ETL execution that created it, and back to the source PDF in cloud storage. This “Glass Box” approach is essential for trust.
6. Case Study Scenarios
6.1 Legal Discovery (The Needle in the Haystack)
- Challenge: A law firm needs to find all contracts with “Force Majeure” clauses that specifically mention “Pandemics,” but only for clients in the “Retail” sector signed after 2020.
- Vector Failure: A vector search for “Pandemic Force Majeure” might return contracts from the “Manufacturing” sector or old contracts, overwhelming the lawyer with irrelevant hits.
- Tabular Solution:
- SQL Filter: WHERE Client_Sector = ‘Retail’ AND Contract_Date > ‘2020-01-01’ (Reduces 100k docs to 500).
- Vector Search: Search for “Force Majeure Pandemic” within the 500 docs.
- Result: 10 highly relevant paragraphs.
- Graph Insight: “Show me other contracts signed by the same signatories.” (Using Entity metadata).
6.2 Engineering Maintenance (The Multi-Hop)
- Challenge: An engineer asks, “Why did the pump fail?”
- Tabular Solution:
- Vector: Find logs describing “pump failure” (Retrieves “Pump A overheated”).
- Graph/Relational: Query Fact_Maintenance_Logs for “Pump A” in the week preceding the failure.
- Result: Identify a log entry: “Technician X skipped calibration.”
- Synthesis: The LLM combines the failure report (unstructured) with the maintenance log (structured) to answer: “The pump likely failed due to overheating caused by skipped calibration on.”
7. Conclusion: The Integrated Future
The integration of non-structured data into the enterprise stack requires us to abandon the notion that text is a “special case” requiring exotic, isolated infrastructure. Instead, we must embrace the Tabular GRAPHRAG paradigm: the rigorous structuring of text into atomic, metadata-rich rows within a converged Lakehouse architecture.
By treating a paragraph as a structured entity—possessing not just text and a vector, but lineage, taxonomy, hierarchy, and relational context—we bridge the gap between the Map and the Territory. We construct a map that is as rich and nuanced as the territory it represents, yet as precise and navigable as a grid.
This architecture—the Tri-Hybrid Engine—orchestrates the determinism of SQL, the semantic intuition of Vector Search, and the connectivity of Knowledge Graphs. It leverages lakehouse platforms—whether Databricks, Snowflake, BigQuery, AWS, Microsoft Fabric, or a fully open-source stack—not just as storage, but as active “Knowledge Factories” that ingest, parse, enrich, and serve intelligence.
For the architect tasked with this integration, the directive is clear: Do not just index your documents. Model them. Parse the territory into rows. Enrich the rows with metadata. And empower your users to navigate the full depth of their institutional knowledge with the precision of a query and the power of an idea.